Gemini 4 Argon Lands at No. 8 on the Frontier AI Benchmark
Google just pushed Gemini 4 Argon into the frontier AI arena, and the top of the board is getting crowded. The Argon (High) variant entered at number 8 on its first showing, and the distance to the leader is now measured in fractions of a percent.
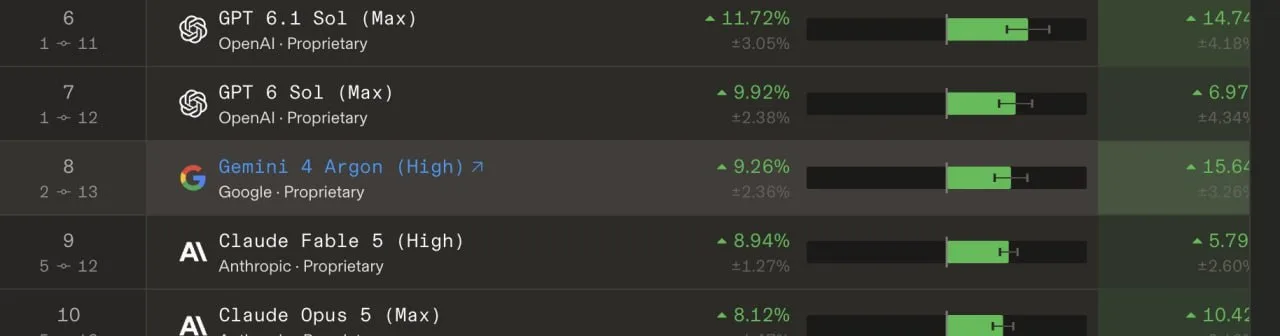
The gap between first and this new arrival is 0.66%. At that margin, the fight at the top is less about raw size and more about how steadily a model holds up on real work.
What Happened
On the latest benchmark board, Argon (High) locked 8th place with a performance score of +9.26% (±2.36%). That puts it above Claude Fable 5 at +8.94% and Claude Opus 5 at +8.12%. It trails GPT 6 Sol, which sits at +9.92%.
Where the gain actually came from matters more than the rank. Google aimed Argon's biggest improvements at long-horizon reasoning, refactoring large codebases, and cybersecurity defense. Those are tasks that run long and punish a model for drifting halfway through.
The variance range is the second number worth a look. At ±2.36%, Argon's output is noticeably steadier than earlier Gemini generations, which means fewer swings between a good answer and a bad one on the same kind of task.
Why It Matters
If you pick models for long jobs rather than one-off prompts, this shifts your shortlist. A 0.66% gap to the top is small enough that consistency, not peak score, becomes the tiebreaker — and a tight variance range is what keeps a multi-step refactor from falling apart at step nine.
The areas Google targeted are also the ones people actually pay for: big code changes and security work. Worth watching how Argon holds up once more of these runs are measured, because the leaderboard's top tier has never been this close.
Does this still work?
Nobody's checked yet
Sign in to tell everyone how it went.
Continue with GoogleBe the first — one tap saves the next person an hour.
It takes 3 reports in 30 days to set the status.
More shares you might like
 ToolsHow to Use Auto Clicker Macro for Android Farming1h5 views
 ToolsHow to Get Free Columbia Online Courses13h11 views
 NewsHelix Foundry Brings Palantir-Style Ontology to Open Source1d31 views
 AIClaude Dashboards and Claude Motion Arrive in Beta2d29 views
 ToolsHow to Get Up to $10,000 in Free Cloudflare Credits3d27 views
 AIHow to Explore AI Cybersecurity With 10 GitHub Repos3d31 views

Comments
Join the conversation — sign in to comment.
No comments yet — start the conversation!