
Google's Harness-Zero Boosts Agent Success Without a Harness
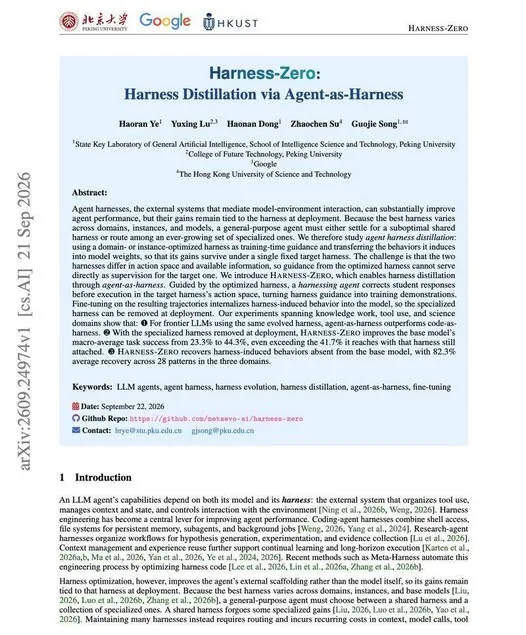
Agent harnesses do a lot of quiet work for AI models, and a new Google paper asks whether the model can just learn that work instead. In the paper's tests, the answer is often yes.
The number worth slowing down for: macro task success moves from 23.3% to 44.3% with the specialized harness removed, which is above the 41.7% the base model reaches with the harness attached.
What Happened
The method is called Harness-Zero, and the trick is timing. The optimized harness is used only during training, never at deployment.
That matters because the optimized harness and the deployment harness have different action spaces. A harnessing agent guided by the optimized harness corrects the student's responses in the deployment action space before those responses run. Those corrected runs then become the training demonstrations.
Across 28 harness-induced behaviors covering knowledge work, tool use, and science, 82.3% are recovered on average. For frontier models using the same evolved harness, the paper also finds that the agent-as-harness form beats the code-as-harness form.
Why It Matters
If this holds up, some of what a harness does today could be baked into the model rather than hand-written around it. That would mean less engineering per task and models that carry more of the workflow themselves.
The authors are upfront that robustness is still an open question. It is early work, but it points at something real: harness distillation is worth watching.
Does this still work?
Nobody's checked yet
Sign in to tell everyone how it went.
Continue with GoogleBe the first — one tap saves the next person an hour.
It takes 3 reports in 30 days to set the status.
More shares you might like
 NewsTanStack Start 1.0 Is Stable20h20 views
 AIDolphin 2.9.2 Runs Uncensored Llama 3 8B on 6GB VRAM20h20 views
 NewsDeepSeek V4 Pro Is a 1.6T Open-Weight Model With a 1M Context1d30 views
 AIHermes 3: An Uncensored 70B Model That Runs on Two GPUs1d25 views
 NewsOpenCode 2.0 Ships Background Tasks and Subagents1d26 views
 AIAlibaba Reveals Qwen4 Series: Max, Plus, Flash and 27B2d37 views

Comments
Join the conversation — sign in to comment.
No comments yet — start the conversation!