
DeepSeek V4 Pro Is a 1.6T Open-Weight Model With a 1M Context
Looking for a frontier-class model you can run on your own hardware? DeepSeek V4 Pro is an open-weight release with an MIT license and no refusal guardrails baked in by the vendor.
You can drive it at native FP8 on 4x 80GB A100 or H100 cards, or fit it on a pair of 24GB RTX 3090 or 4090 cards if you drop to a 4-bit quant.
What Happened
DeepSeek V4 Pro uses a mixture-of-experts architecture: 1.6T total parameters, with 236B active at a time. It ships under an MIT license, so the weights are open and there are no built-in refusal guardrails from the vendor.
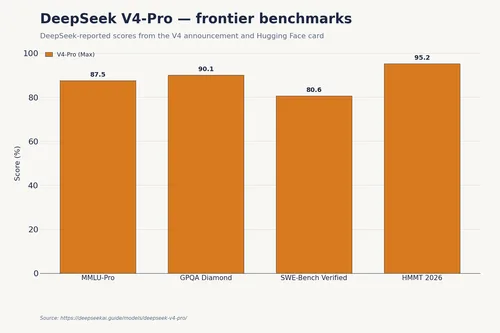
The native context window is 1M tokens, and it scores 80.6% on SWE-Bench Verified. The source recommends it for autonomous coding, deep reasoning, and cyber research.
Why It Matters
The weights are open; the hardware is not. Here is what the source says it takes to run:
- VRAM: 4x 80GB (A100 or H100) for native FP8, or 2x RTX 3090 or 4090 at 24GB for 4-bit quant formats such as GGUF or EXL2.
- System RAM: 512GB if you are offloading to the CPU.
- Storage: about 1.2TB for the full FP16 weights, or roughly 180GB to 250GB for the FP4 or Q4 quantized versions.
- PCIe bandwidth: Gen 4 or Gen 5 is strongly recommended for inter-GPU communication.
If you are weighing local inference against an API, those numbers are the deciding factor.
Does this still work?
Nobody's checked yet
Sign in to tell everyone how it went.
Continue with GoogleBe the first — one tap saves the next person an hour.
It takes 3 reports in 30 days to set the status.
More shares you might like
 ToolsHow to Use Rich Clicker Macro's Smart Auto Clicker7h16 views
 AIHow to Install hyperresearch for Deep Research in Claude Code2d34 views
 ToolsHow to Set Up Free Temp Email With XTemp Mail2d43 views
 NewsGrabFood Vermuk Bypass: No Working Termux Script Exists3d41 views
 ToolsHow to Self-Host Apps and Databases With Dokploy3d48 views
 News44 AI Agents Ran a Hacking Campaign Against Japan4d53 views

Comments
Join the conversation — sign in to comment.
No comments yet — start the conversation!