
GLM-5.3 Benchmarks Show Major Leaps in Coding and Security
If you have been waiting for an open-weights model you can actually run locally, GLM-5.3 from Z.ai is starting to look like the one. The benchmark numbers just dropped, and they show huge jumps in coding and offensive security.
Those gains are concrete, and the weights land in two weeks.
What Happened
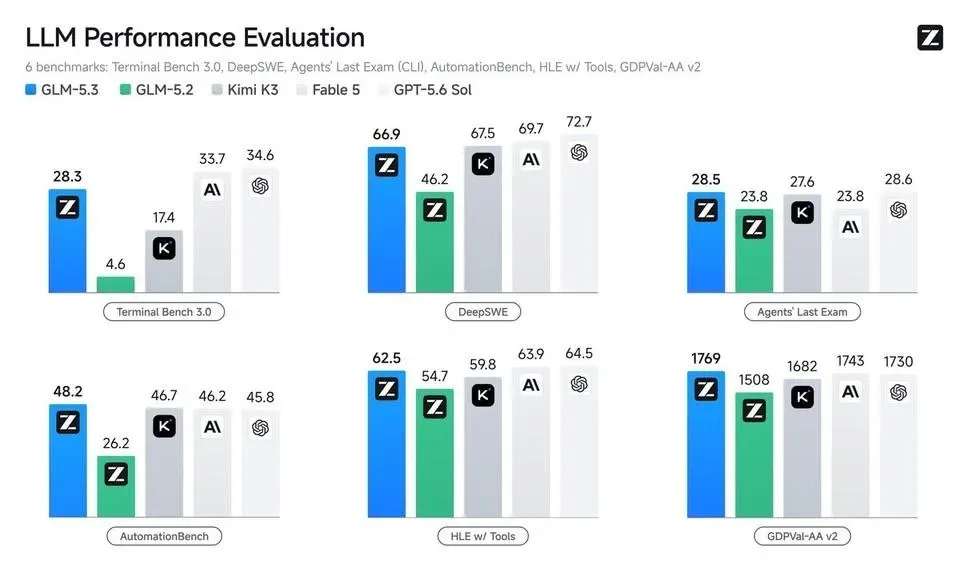
Z.ai shared early benchmark results for GLM-5.3, an upcoming open-weights model. The numbers are a clear step up from earlier versions:
- Terminal Bench 3.0: jumped from 4.6 to 28.3
- DeepSWE v1.1: rose from 46.2 to 66.9
- Internal Code Bench: about 50% higher than GLM-5.2
- AutomationBench: 48.2, topping the chart
- GDPVal-AA v2: 1769, also at the top
The security results are the standout. CyberGym scored 84.5, beating GPT-5.6 Sol's 83.6. ExploitBench hit 54.4, a 2x improvement. In real-world testing, the model found 2,436 vulnerabilities across 269 active projects.
Weights are scheduled to release in two weeks.
Why It Matters
This is a strong signal that scaling post-training matters as much as the architecture itself. Once the weights drop, you will be able to run a model locally that competes with closed models on coding and security work.
Does this still work?
Nobody's checked yet
Sign in to tell everyone how it went.
Continue with GoogleBe the first — one tap saves the next person an hour.
It takes 3 reports in 30 days to set the status.
More shares you might like
 ToolsHow to Get 12 Months of Adobe Express Premium Free32m2 views
 ToolsHow to Use Group By in Amazon Associates Reports1d38 views
 ToolsHow to Make Fireworks AI Videos With ChatGPT and Flow1d27 views
 AIAnthropic's AI-Native SDLC Playbook, Explained3d41 views
 NewsTanStack Start 1.0 Is Stable4d51 views
 AIDolphin 2.9.2 Runs Uncensored Llama 3 8B on 6GB VRAM4d40 views

Comments
Join the conversation — sign in to comment.
No comments yet — start the conversation!