
DFlash 2 Speeds Up Local AI by Up to 4.6 Times
Local AI just got a major speed boost, and the new tech is free. Inco AI and Z Lab say their DFlash 2 generation doubles local AI speed by up to 4.6 times.
The headline number: Qwen3.8-27B runs at 70 tokens per second on an M5 Max MacBook Pro.
What Happened
Inco AI, working with Z Lab, launched DFlash 2, the latest version of its generative technology. The team says it doubles the speed of local AI by up to 4.6 times. They demonstrated it running the Qwen3.8-27B model at 70 tokens per second on an M5 Max MacBook Pro, calling the result a legendary leap. The announcement presents DFlash 2 as a go-to tool for developers.
Why It Matters
Token speed is the bottleneck for local AI. If DFlash 2 really delivers that 4.6x gain, developers can run large models like Qwen3.8-27B at usable speeds on a laptop, without paying for cloud GPUs. That makes local development more practical for a lot of teams. The post does not include setup instructions, so the how-to is still to come.
More shares you might like
 ToolsHow to Make Motion Graphics Videos With Claude1d33 views
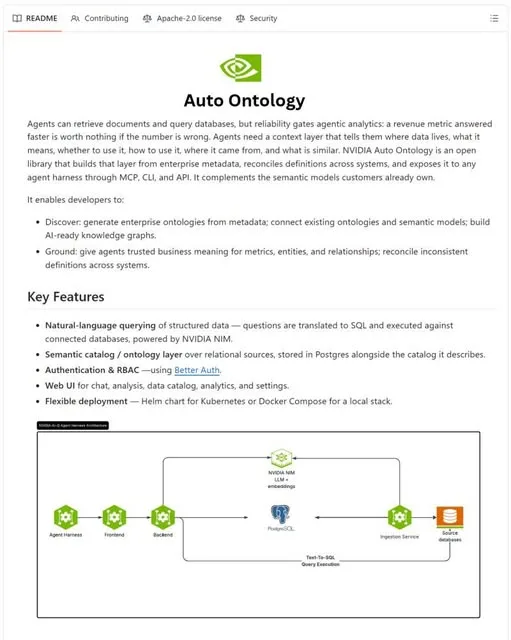 NewsNVIDIA Open-Sources Auto Ontology, a Semantic Layer for AI Agents2d46 views
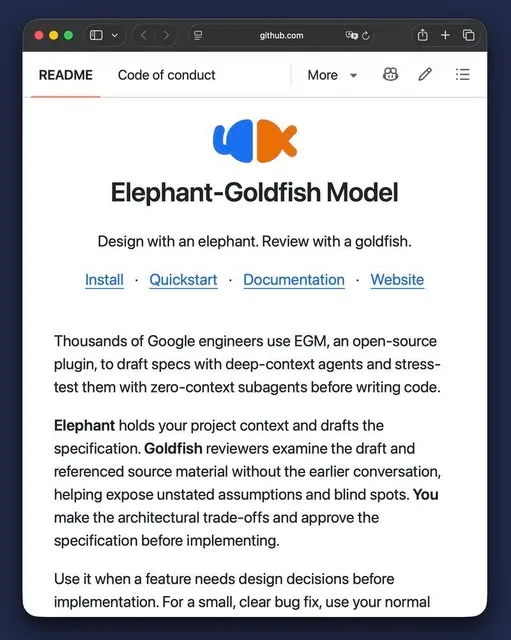 ToolsHow to Write Specs Coding Agents Can Build Without Guessing3d50 views
 AIParallel's Decisions API Grounds Decision Models With Live Web Search4d55 views
 How to Claim 1B Muse AI Tokens4d103 views
 ToolsHow to Use Rich Clicker Macro's Smart Auto Clicker5d59 views

Comments
Join the conversation — sign in to comment.
No comments yet — start the conversation!