DeepSeek V4 Flash Runs on 8GB RAM With No GPU
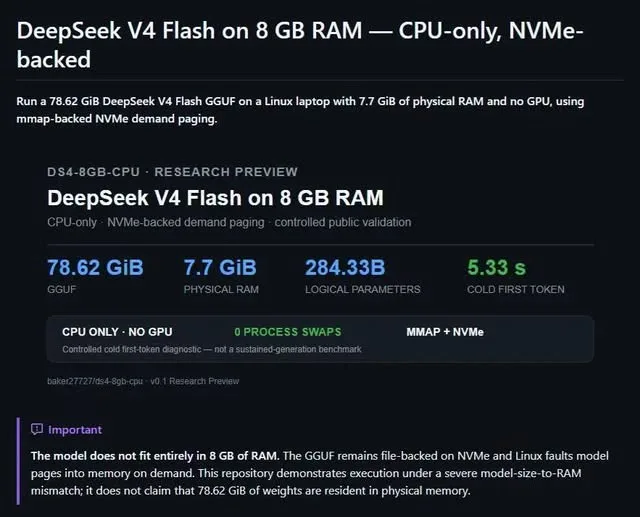
Running a 79 GB AI model on a machine with 8 GB of RAM and no GPU sounds impossible. DeepSeek V4 Flash just did it using a memory-mapped GGUF file on an NVMe SSD.
What Happened
DeepSeek V4 Flash has 284.33 billion parameters and ships as a 78.62 GiB GGUF quant. The test rig used 8 GB RAM, CPU-only processing, and an NVMe SSD — no CUDA, no GPU. Linux mapped the GGUF file into virtual memory and used demand paging to load only the active weights into RAM. The result: a first-token diagnostic at around 5.33 seconds, with a resident set size of about 5.9 GiB and no process swaps.
Why It Matters
This setup does not promise chat-speed performance. The developer says sustained decoding speeds are not assured, and the 5.33-second number comes from a controlled first-token test, not real conversation latency. Still, it shows that a model too big for RAM is a performance problem, not a hard wall. As smart paging, MoE expert loading, and faster NVMe drives improve, SSDs will become a real part of the local AI memory stack alongside VRAM and RAM.
Does this still work?
Nobody's checked yet
Sign in to tell everyone how it went.
Continue with GoogleBe the first — one tap saves the next person an hour.
It takes 3 reports in 30 days to set the status.
More shares you might like
 AIHow to Get Free $200 Funds on Digital Ocean1y781 views
 ToolsHow to Use GPT-5.6 and Claude for Free on Duck.ai1w71 views
 ToolsHow to Avoid 5 Amazon Associates Registration Mistakes3w58 views
 ToolsHow to Get Free Cursor Pro by Switching Subscriptions2w99 views
 AIHow to Claim 10k Free AI Video Credits1mo91 views
 AIPlayco Reports 50% Fewer Manual Fixes With GPT-6 Astra4d28 views

Comments
Join the conversation — sign in to comment.
No comments yet — start the conversation!